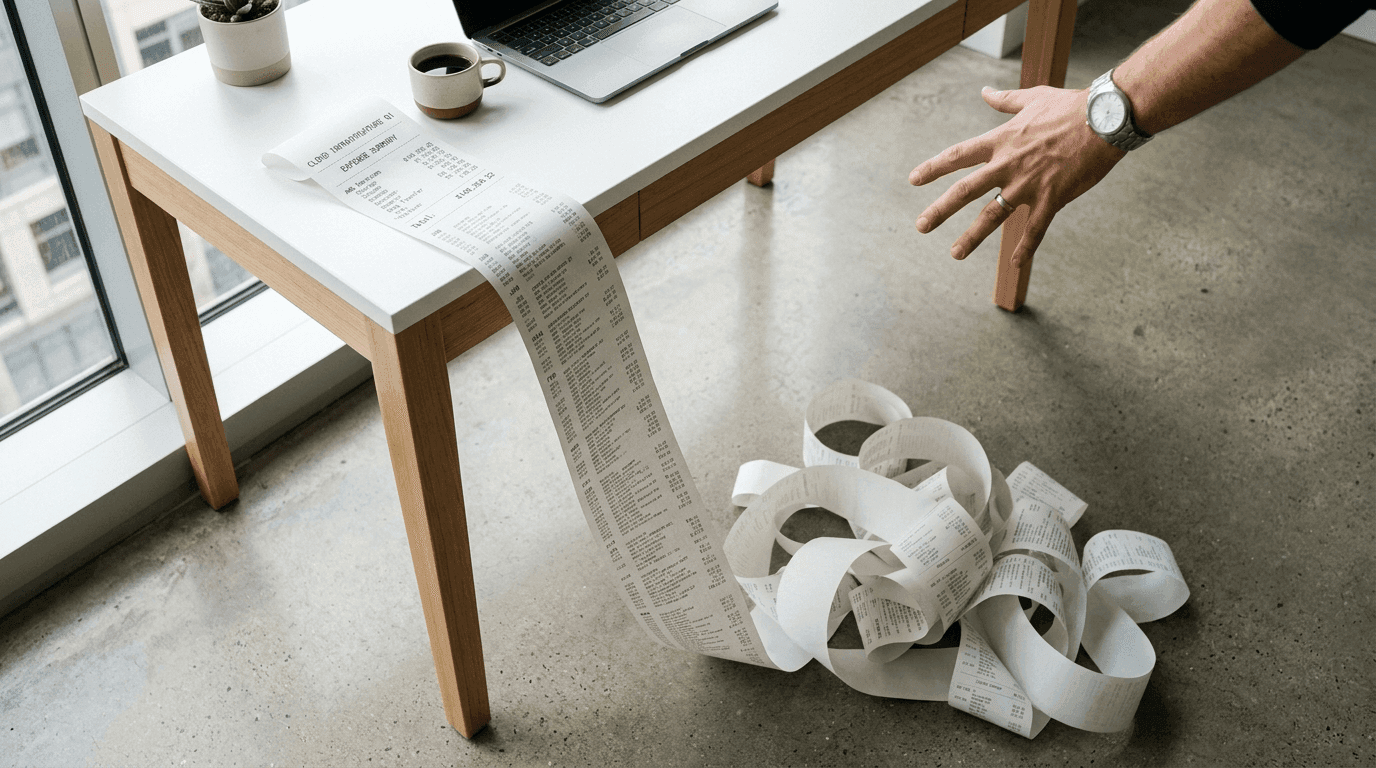
Here is a number that should get your attention. Your development, QA, and staging environments are probably running 168 hours a week. How many of those hours does anyone actually use them?
If your team works standard business hours - 9 to 6, Monday through Friday - that's 45 working hours. The rest, roughly 123 hours of EC2 instances, RDS databases, and EKS nodes, are sitting idle, burning budget, and doing absolutely nothing.
AWS's own documentation states it plainly: moving dev/test instances from 24/7 to a business-hours schedule reduces running time from 168 to roughly 50 hours per week - up to 70% savings on those instance hours. One DevOps consultancy applied this to 13 testing and staging environments and saved $40,000 per year. This is not a sophisticated optimization. It is an alarm clock for your cloud.
The Math - And Why Most Teams Don't Act on It
Let's make the numbers concrete. Take a typical dev environment with five m5.xlarge EC2 instances at $0.192/hr each and two db.t3.medium RDS instances at $0.068/hr each. Running 24/7, that's about $801/month.
Apply a business-hours schedule - 9am to 6pm weekdays, roughly 45 hours per week. Monthly running hours drop from 730 to ~195. Monthly cost drops to around $214. That's $587/month per environment, or over $7,000 per year from a single dev environment.
Scale that across five dev and QA environments and you're looking at $35,000+ per year - from adding tags and writing two Lambda functions.
Why don't most teams do this? Three reasons. They don't know the numbers. Someone is worried about disrupting developers. And nobody has documented the right approach for stateful services, pipeline dependencies, and time zones. This guide covers all three.
Option 1: AWS Instance Scheduler v3 - The Official Path
If you want a supported, multi-service, multi-account scheduler backed by AWS and operated via a proper CloudWatch dashboard, AWS Instance Scheduler v3 is the answer.
What it supports: EC2, RDS, Neptune, DocumentDB, and Auto Scaling Groups. Multi-account and multi-region via a hub-and-spoke CloudFormation deployment. Optional EC2 hibernation. KMS integration for encrypted EBS volumes. Solution overhead is roughly $13/month - negligible against any realistic compute savings.
How it works: Deploy the CloudFormation template to create the hub stack. Resources get a tag (such as "Schedule=office-hours"). Lambda functions run on a configurable interval, read schedules from DynamoDB, and call the appropriate start/stop APIs while emitting CloudWatch logs and metrics per schedule.
- ASG support via automatic Scheduled Scaling Rules
- Neptune and DocumentDB cluster scheduling
- Operational Insights CloudWatch dashboard
- Multiple maintenance windows per schedule
- IS-ManagedBy, IS-LastAction, and IS-Error tags on managed resources for per-resource observability
- Tag-change event detection - newly tagged instances are picked up automatically
When to choose this option: When you need multi-account and multi-region control, want an AWS-supported solution with proper upgrade paths, and are comfortable with CloudFormation as the deployment mechanism.
Option 2: Lambda + EventBridge - Build It Yourself
For teams who want full control, a simpler mental model, or tighter Terraform integration, the Lambda + EventBridge pattern is the most widely adopted approach in production environments.
The pattern is straightforward. Tag resources you want to control (for example "AutoShutdown=true" and "Environment=dev"). Write a Lambda function that finds tagged resources and stops them. Write another that starts them. Create EventBridge cron rules pointing at each function. Done.
Here is a production-ready Python Lambda for stopping EC2 instances:
import boto3
import logging
import os

logger = logging.getLogger()
logger.setLevel(logging.INFO)

REGION = os.getenv("AWS_REGION", "us-east-1")


def lambda_handler(event, context):
    ec2 = boto3.client("ec2", region_name=REGION)

    try:
        paginator = ec2.get_paginator("describe_instances")

        instance_ids = []

        for page in paginator.paginate(
            Filters=[
                {"Name": "instance-state-name", "Values": ["running"]},
                {"Name": "tag:AutoShutdown", "Values": ["true"]},
            ]
        ):
            for reservation in page["Reservations"]:
                for instance in reservation["Instances"]:
                    instance_ids.append(instance["InstanceId"])

        if not instance_ids:
            logger.info("No instances to stop")
            return {"stopped": []}

        logger.info("Stopping %d instances: %s", len(instance_ids), instance_ids)

        ec2.stop_instances(InstanceIds=instance_ids)

        return {"stopped": instance_ids}

    except Exception as e:
        logger.exception("Shutdown failed")
        raise
And the Terraform to wire it up:
# Stop at 7pm UTC weekdays
resource "aws_cloudwatch_event_rule" "stop_dev" {
  name                = "stop-dev-instances"
  schedule_expression = "cron(0 19 ? * MON-FRI *)"
}

resource "aws_cloudwatch_event_target" "stop" {
  rule = aws_cloudwatch_event_rule.stop_dev.name
  arn  = aws_lambda_function.stop_instances.arn
}

# Start at 7am UTC weekdays
resource "aws_cloudwatch_event_rule" "start_dev" {
  name                = "start-dev-instances"
  schedule_expression = "cron(0 7 ? * MON-FRI *)"
}

resource "aws_cloudwatch_event_target" "start" {
  rule = aws_cloudwatch_event_rule.start_dev.name
  arn  = aws_lambda_function.start_instances.arn
}
The same pattern applies to RDS - swap "stop_instances" for "stop_db_instance" and filter by DBInstanceStatus "available." One important RDS quirk: AWS allows RDS instances to be stopped for a maximum of 7 consecutive days, after which they automatically restart. Schedule a Lambda to re-stop any instances that have auto-restarted on an off-hours day.
Option 3: Terraform Community Modules
Rather than writing Lambda functions from scratch, several well-maintained Terraform modules package this pattern and are actively used in production.
The most comprehensive option is the padok-team/terraform-aws-start-stop-scheduler module. It supports ASGs, EKS node groups, RDS, and EC2. It suspends and resumes ASGs, controls RDS stop/start, and can terminate tagged EC2 instances at shutdown for maximum savings. Here is a minimal configuration:
module "dev_scheduler" {
  source  = "padok-team/start-stop-scheduler/aws"
  version = "~> 2.0"

  name = "dev-environment-scheduler"

  # Stop 8pm UTC weekdays, start 7am UTC weekdays
  stop_schedule  = "cron(0 20 ? * MON-FRI *)"
  start_schedule = "cron(0 7 ? * MON-FRI *)"

  ec2_schedule = true
  rds_schedule = true
  asg_schedule = true

  resources_tag = {
    key   = "Environment"
    value = "dev"
  }
}
Other modules worth knowing:
- eanselmi/terraform-aws-ec2-rds-scheduler - Provisions eight Lambda functions (start/stop for EC2, ASG, RDS, and Aurora) with EventBridge schedules. Config driven by cron expressions and tag maps.
- telia-oss/terraform-aws-ec2_scheduler - Uses "start_at" and "stop_at" tags directly on instances (hours 0–23). Hourly EventBridge polling, clean tag-driven interface.
- barryw/rds-scheduler/aws - Terraform Registry module focused on RDS instances and clusters for dev and staging use cases.
Handling Stateful Services: RDS
RDS has a quirk worth knowing before you implement. You can stop an instance for a maximum of 7 consecutive days. After that, AWS automatically starts it regardless. For most scheduling scenarios this is irrelevant, but a long holiday weekend can catch you off guard.
The fix is simple: schedule a Lambda to run every 6 days that stops any dev RDS instances that have quietly auto-restarted.
What you are still billed for while stopped: Storage, Provisioned IOPS, and automated backup storage continue to accrue. Instance compute charges stop. For most dev databases, compute is the dominant cost - stopping instances during off-hours can deliver roughly 76% compute savings while accepting ongoing storage charges.
- Tag production databases explicitly and exclude them from all stop/start automation without exception
- Coordinate stop schedules with automated backup windows - AWS will not stop an instance during a backup, so schedule stops at least 30 minutes after backup windows close
- Build retry logic and startup health checks into application services - dev services that start at 7am before RDS is fully available (startup takes 1–3 minutes) will fail without proper connection retry logic
- Consider Aurora Serverless v2 for truly intermittent dev workloads - it scales to a minimum ACU automatically during idle periods without requiring a stop/start scheduler
Handling Stateful Services: ElastiCache
ElastiCache is the awkward one. You cannot stop an ElastiCache cluster - AWS does not support it. Your options are scaling down or deleting and recreating.
For dev and QA Redis clusters where a few minutes of startup delay each morning is acceptable, the snapshot-delete-recreate approach delivers near 100% overnight compute savings. You pay only for snapshot storage.
import boto3
from datetime import datetime

def stop_elasticache_cluster(cluster_id: str) -> str:
    """Snapshot and delete an ElastiCache cluster for overnight savings."""
    client = boto3.client('elasticache')
    snapshot_name = f"{cluster_id}-{datetime.now().strftime('%Y%m%d')}"

    client.create_snapshot(
        CacheClusterId=cluster_id,
        SnapshotName=snapshot_name
    )

    # Wait for snapshot completion before deleting
    waiter = client.get_waiter('snapshot_complete')
    waiter.wait(SnapshotName=snapshot_name)

    client.delete_cache_cluster(CacheClusterId=cluster_id)
    return snapshot_name
One other option worth considering: migrate dev clusters from Redis OSS to ElastiCache for Valkey. AWS announced up to 60% cost savings with Valkey even before any scheduling changes are applied. For smaller organizations, that single migration may be more impactful than building a delete/recreate workflow.
EKS Cluster Scale-to-Zero
Kubernetes adds complexity because stopping "nodes" means scaling node groups to zero - the EKS control plane keeps running and accruing charges (~$0.10/hour) regardless. Budget for that.
Approach A: Managed Node Group scaling via Lambda
An EventBridge rule triggers a Lambda at night that sets the desired capacity of each managed node group to zero. Another rule restores it in the morning.
import boto3

def scale_eks_nodegroup(cluster: str, nodegroup: str, desired: int):
    eks = boto3.client('eks')
    eks.update_nodegroup_config(
        clusterName=cluster,
        nodegroupName=nodegroup,
        scalingConfig={'minSize': 0, 'maxSize': 10, 'desiredSize': desired}
    )

# Evening: scale to zero
scale_eks_nodegroup('dev-cluster', 'general-workers', 0)

# Morning: restore
scale_eks_nodegroup('dev-cluster', 'general-workers', 3)
Approach B: Karpenter + kube-downscaler
Scale all Deployments to zero replicas at night using kube-downscaler. With Karpenter watching pod demand, it automatically terminates nodes when no pods need scheduling. In the morning, workloads scale back up and Karpenter provisions fresh nodes in roughly 55 seconds.
Approach C: EKS Auto Mode (November 2024)
Amazon EKS Auto Mode, launched at re:Invent 2024, abstracts away node group management entirely. It provisions and removes nodes based on pod demand, eliminates idle nodes automatically, and selects instance types including Spot automatically. Combined with KEDA-based workload scale-to-zero, Auto Mode can approach near-zero dev cluster costs without custom cron jobs.
Important caveat before scaling to zero: Audit your cluster add-ons. Ingress controllers, monitoring agents, and CoreDNS may need at least one small On-Demand node to remain available. Test cold-start time end-to-end before rolling out to a full team - developers need to know what startup delay to expect each morning.
re:Invent 2024: Free Idle Resource Detection
One of the most useful improvements from re:Invent 2024 for environment scheduling has nothing to do with schedulers directly: AWS Compute Optimizer now surfaces idle resource recommendations that highlight idle EC2 instances, ASGs, EBS volumes, ECS services on Fargate, and RDS instances - with total savings potential from stopping or deleting them.
Run this weekly before your implementation work. It gives you a prioritized list of resources safe to add to your scheduler with concrete savings estimates. It is free and available in the Compute Optimizer console today.
The re:Invent 2024 updates also included DynamoDB on-demand throughput price reductions of 50% and new Aurora and RDS performance improvements - context that shifts the cost calculus slightly for some workloads, but the fundamental scheduling math remains the same.
The Auto-Stop Checklist
Work through this before go-live. Skip a step and you will receive an angry Slack message from a developer at 7:30am.
Planning
Inventory all non-production environments: dev, QA, staging, load testing, sandbox Map every resource per environment: EC2, RDS, ElastiCache, EKS node groups, ECS services Document production resources explicitly and exclude them from all automation Define schedule in UTC: start time, stop time, weekend behavior Design override mechanism: "KeepRunning=true" tag for exceptions Communicate schedule to developers before rollout Implementation
Apply "AutoShutdown=true" tags to all in-scope resources Deploy Lambda functions or Instance Scheduler with least-privilege IAM roles Test stop/start on a single environment for one full cycle before wide rollout Verify RDS backup windows do not overlap with stop schedule Add connection retry logic to application startup sequences Set up ElastiCache snapshot-delete or scale-down workflow Configure CloudWatch alarms for failed stop/start Lambda executions EKS-Specific
Audit cluster add-ons for always-on requirements before scaling to zero Configure Karpenter or Cluster Autoscaler to scale down when no pods are pending Test cold-start time end-to-end for each dev cluster Evaluate EKS Auto Mode for new dev clusters Operations
Document how developers can request a one-time schedule override Track monthly savings per environment in your cost dashboard Review schedules quarterly - development patterns change over time Frequently Asked Questions
Will auto-stopping break our CI/CD pipelines?
Only if your pipelines are scheduled to run outside business hours without you realizing it. Audit your pipeline schedules before implementing. Move any overnight jobs to run within your defined window, or add logic to start the environment, run the pipeline, then stop it automatically when the job completes.
Our team spans multiple time zones. How do we handle the schedule?
Define your schedule in UTC and be explicit in documentation. If you have engineers in Tokyo and New York, your business hours window expands significantly. Consider an extended window - for example 6am to 11pm UTC - that covers both regions, then progressively tighten it as you build confidence in the savings and confirm nobody is working outside it.
Can we apply this to production to save on overnight costs?
Generally no - production services need to be available for users around the clock. But there are exceptions: batch processing jobs, ETL pipelines, and ML training workloads can run on a schedule and stop when complete. Aurora Serverless v2 is the right answer for production databases with genuinely unpredictable traffic patterns.
How much can we realistically save?
For standard dev and test workloads, expect 60–70% savings on compute for the scheduled environments. Moving from 168 to 50 hours per week saves 70% on instance charges. Storage, EBS volumes, and backup storage continue to accrue but are typically a small fraction of total environment cost. For a company with 10 reasonably sized dev and QA environments, this optimization commonly saves $50,000–$150,000 per year.